Inference
Faster inference on the GPUs you already have
See a dip in an inference metric? Click it and drill into the full-stack code behind it to understand why. The same rich context lets AI agents optimize the code in one shot.
- No code changes
- Root cause down to the kernel
- Fixes your agents can ship
 Dynamo-Triton TensorRT-LLM
Inside the engine
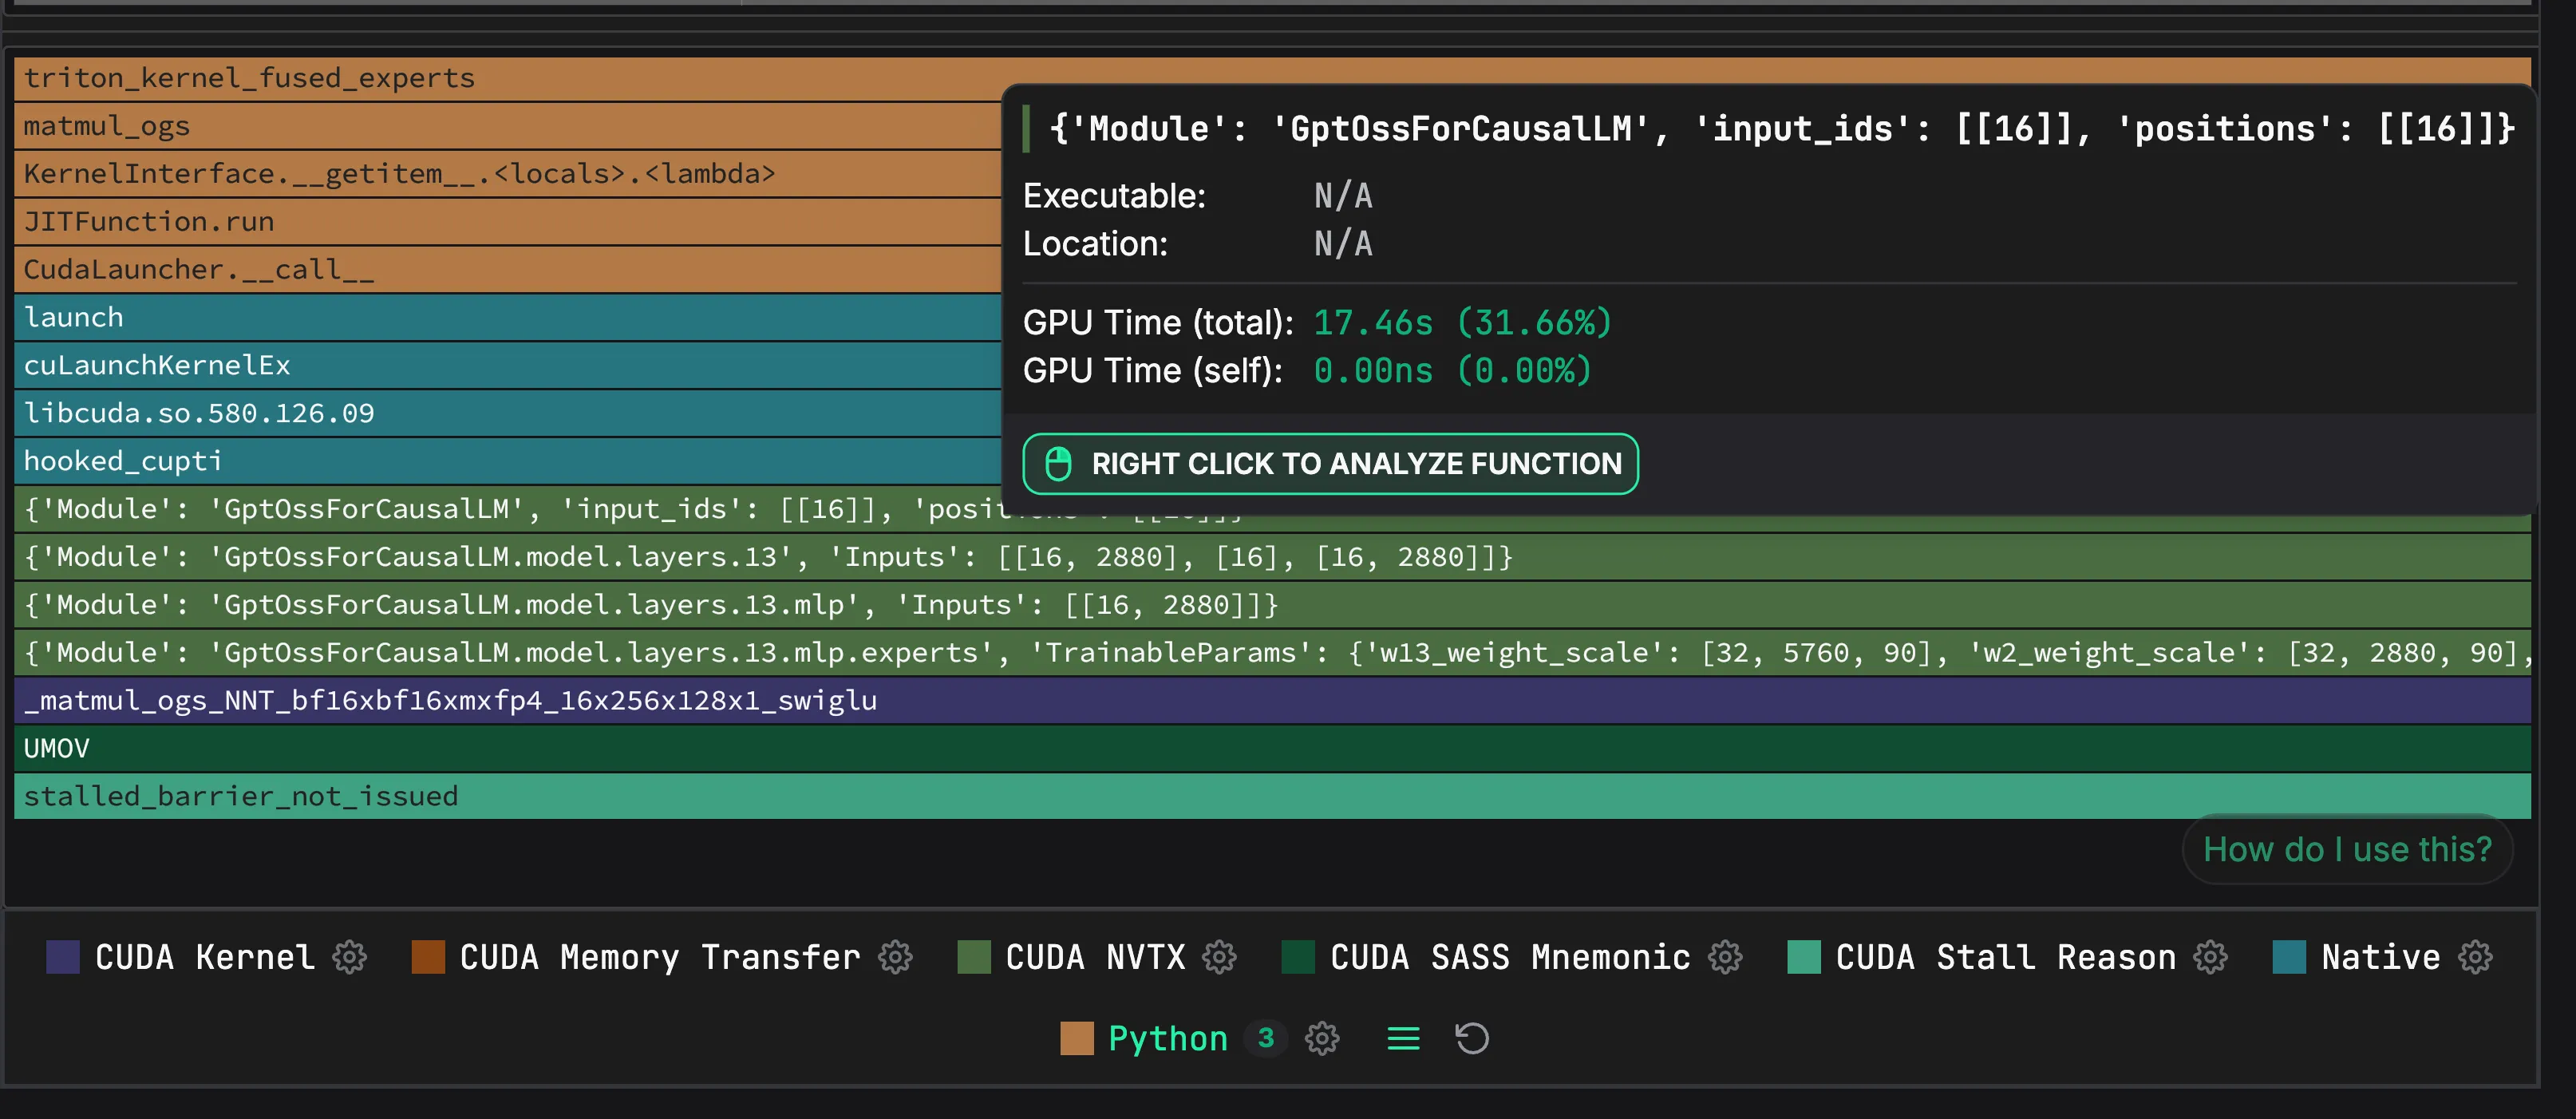
See which model layer each kernel belongs to
Inference kernels are named after math, not your model. NVTX ranges or model shapes add the layer, submodule and input shapes behind each kernel.
- On gpt-oss-20b in vLLM, the
mlp.expertsscopes took about 77% of GPU time - CUDA graphs are sampled, and a sampled launch profiles the whole graph
- vLLM's tensor- and pipeline-parallel layout on the Models page
Customer results
Lower latency, higher throughput
Anam, real-time interactive avatars
Anam traced slow avatar inference to Python runtime overhead and GIL contention, then removed it with TorchScript and CUDA graphs.
- lower latency
- 2.5×
- inference throughput
- +90%
TypeSafe profiled Jev's training and inference with Zymtrace. Three optimizations compounded on the same hardware, and removing a hidden device-to-host sync sped up inference.
- training throughput
- +46%
- faster inference
- ~10%
FAQ
Inference FAQ
No. Profiles need no code changes, and engine metrics come from the server's Prometheus endpoint. SGLang only needs
--enable-metrics.vLLM and SGLang, with HIP graphs. NVIDIA Dynamo-Triton and TensorRT-LLM are NVIDIA-only.
Yes. Graph launches are sampled, 20 per thread per second by default, and a sampled launch profiles the whole graph.
GPU profiles and GPU metrics. Zymtrace doesn't collect engine metrics from TensorRT-LLM.
Yes. Over MCP, coding agents correlate vLLM, SGLang and Dynamo-Triton metrics with the GPU flamegraphs.
Profile your inference fleet
Zymtrace is fully self-hosted. 5 minutes is all you need to get it up and running.